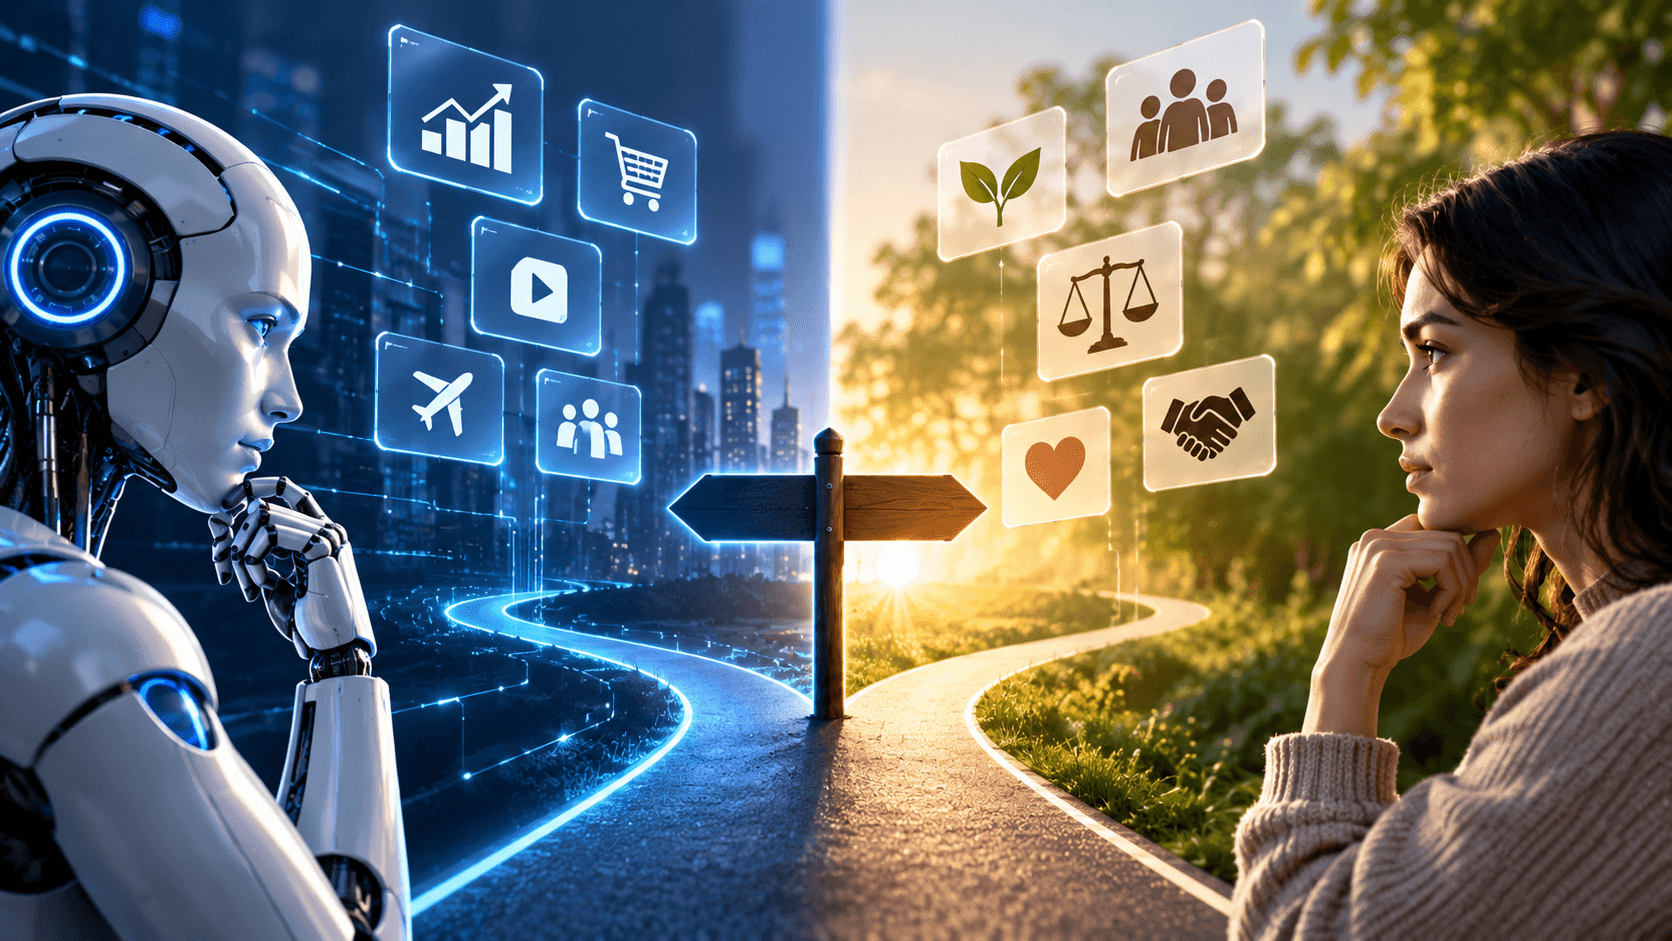
When the algorithm disagrees with your values, who wins?
A promotion model at a large services firm did exactly what it was trained to do. It ranked candidates for a senior role by predicted performance, and it ranked them well. Then a hiring committee noticed something the model could not: the top-ranked candidate had a pattern of burning out the people around them, and the person ranked fourth had quietly built three of the company's strongest teams. The model saw output. The committee saw values. The uncomfortable question was who got the final say.
Every organisation adopting AI for people decisions will eventually hit this moment. The algorithm will recommend something efficient, defensible on the data, and quietly at odds with what you say you stand for. When that happens, the design question is no longer "is the model accurate?" It is "who wins, the model or the value?" And the honest answer is that most companies have never decided in advance.
"The model advises. The human decides. That ordering is a values statement — and it should be as fixed as any line in your code of conduct."
— peopleHum, "When the algorithm disagrees with your values, who wins?"The myth of the neutral recommendation
The first trap is believing the algorithm is neutral and your values are the bias. It is usually the reverse. A model learns from your history, and your history contains every shortcut, every bias, and every expedient decision your organisation ever made. If you promoted people who worked the longest hours, the model will learn that presenteeism predicts success. If your past hiring favoured a certain pedigree, the model will faithfully reproduce it and dress it up as merit.
So when the algorithm disagrees with your stated values, it is often surfacing the gap between what you say you value and what you have historically rewarded. That is not a reason to ignore the model. It is a reason to treat its disagreement as diagnostic. The value should win — but the disagreement should trigger an honest look at whether the value was ever really operating.
Build the veto before you need it
Human oversight that is invented in the middle of a crisis is not oversight; it is improvisation. Design the override before the model ships, not after it recommends something you regret. Three mechanisms belong in every AI-driven people decision, and you should write them down, not assume them.
Override. A named human role has the explicit authority to reject an AI recommendation, and the system is built to accept that rejection without friction. If overriding the model requires a support ticket and a week, the model has effectively won by default.
Escalation. Clear thresholds define which decisions cannot be made by the model alone. High-stakes calls — terminations, promotions, pay, and performance ratings that affect someone's livelihood — route to a human by design, every time, not just when someone remembers to check.
Human veto. On the decisions that touch dignity and fairness most directly, a person holds a final, non-negotiable stop button. The model advises. The human decides. That ordering is a values statement, and it should be as fixed as any line in your code of conduct.
Emerging regulation is moving firmly in this direction. Frameworks like the EU AI Act classify AI used in hiring and employment as high-risk and require meaningful human oversight rather than rubber-stamping. Building the veto is no longer just good ethics; it is fast becoming table stakes for compliance.
Rubber-stamping is the real failure mode
Here is the danger nobody puts on a slide: the human in the loop who always says yes. Automation bias is well documented — when a confident system makes a recommendation, tired people under time pressure tend to defer to it, even against their own judgment. A veto that is never exercised is not oversight. It is theatre that transfers accountability to a human while leaving the machine in charge.
Picture a manager handed a dashboard of AI-generated performance rankings twenty minutes before calibration. They have forty people to review and no time to interrogate the logic. They approve the list. Technically, a human decided. In reality, the algorithm did — and the manager now owns an outcome they never actually examined.
"If your reviewers don't have time to review, information to challenge, and safety to disagree, you don't have human judgment in the loop — you have human liability in the loop."
— peopleHum, "When the algorithm disagrees with your values, who wins?"Track your override rate. If it is zero, that is not a sign the model is perfect. It is a sign the veto isn't real.
Explainability makes disagreement possible
You cannot overrule what you cannot understand. If a model recommends declining a candidate or flagging an employee as a flight risk, the reviewer needs to know why in terms a human can weigh. "The model gave a score of 0.34" is not a reason anyone can argue with. "The model weighted tenure heavily and this person changed jobs twice" is something a human can look at and say, "in this case, that's the wrong signal."
Explainability turns a black box into a colleague you can argue with. It is the precondition for meaningful disagreement — and disagreement is precisely where your values get to win. A model that cannot explain itself quietly removes the human's ability to apply judgement at all.
Decide who wins before the machine asks
So who wins when the algorithm disagrees with your values? On matters of efficiency, scheduling, and routine ranking, let the model lead — that is what it is for, and second-guessing it everywhere recreates the bottleneck you automated away. But on matters of fairness, dignity, and who gets a chance, the value wins, every time, by design. That is not indecision. It is the whole point of keeping humans in the loop.
The organisations that will trust their AI five years from now are the ones building the override, the escalation path, and the human veto today — and, crucially, using them. They treat every disagreement between the model and their values as a moment of truth rather than an error to be smoothed over.
peopleHum is built so that AI amplifies human judgement instead of overruling it — surfacing insight, flagging risk, and speeding the routine, while keeping people firmly in control of the decisions that define your culture. If your current tools make it easy to defer to the algorithm and hard to override it, that balance is backwards. The right platform makes the human decision the easy path and the audit trail automatic, so overriding the model is a click and a comment, not a fight against the workflow. Design the veto before you need it, and make sure your values never lose by default.
Disagreement is diagnostic. When the algorithm clashes with stated values, it is often exposing the gap between what you say you value and what you have historically rewarded — a prompt to check whether the value was ever really operating.
Design the veto before you need it. The override, the escalation path, and the human veto must be built before the model ships — not improvised after it recommends something you regret.
A yes-every-time human isn't oversight. Automation bias is real; under time pressure people defer to confident systems. If the override rate is zero, the veto is theatre, not control.
Explainability is the precondition for disagreement. You can't overrule what you can't understand; a model that can't explain its reasoning strips away human judgment entirely.
Efficiency to the model, dignity to the value. Let the model lead on routine ranking; on fairness and who gets a chance, the value wins every time — an ordering as fixed as your code of conduct.